RPA and agentic AI get pitched against each other more often than they should. In practice, the pairing works better as a pipeline than a competition — and a telecom service disconnect workflow is a clean example of why.
Why RPA and agentic AI belong in one pipeline
Most conversations about agentic AI treat RPA like the old technology it’s replacing. That’s backwards. In the programs I’ve been closest to, the two work best side by side, and the reason comes down to something rarely discussed: token economics.
An AI agent is expensive and slow when you ask it to do deterministic work. Reading a folder of PDFs, scraping a legacy system export, converting an unstructured file into a clean structured record: none of that requires reasoning. It requires consistency, and that’s exactly what RPA has always been good at.
So instead of routing everything through an LLM, the smarter architecture lets the RPA bot handle ingestion (reading files, cleaning data, converting unstructured input into structured output) and then hands that clean, structured data to the AI agent. The agent’s reasoning power, and its token budget, is reserved for the part that actually needs judgment: categorization, decision-making, exception handling and next-best-action.
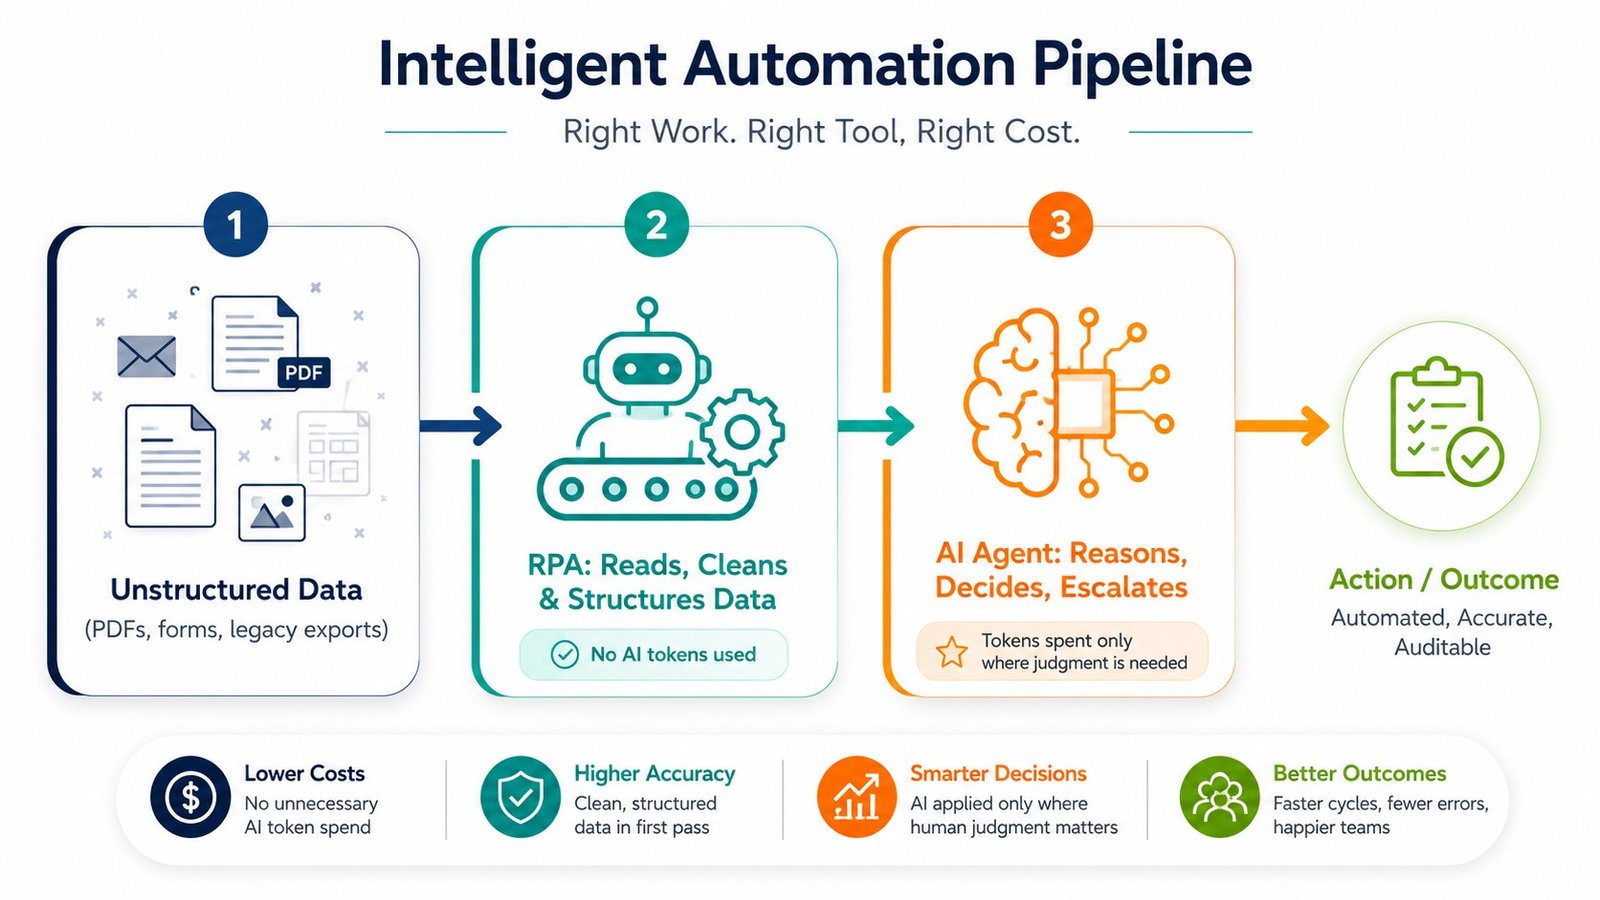
The result isn’t just cheaper. It’s more reliable. You’re not asking a probabilistic system to do a deterministic job, and you’re not asking a rules engine to make a judgment call it was never built for.
A real example: a telecom service disconnect
A telecom enterprise customer submits a disconnect request: hundreds of services, across multiple accounts and sites, arriving as email, PDFs, spreadsheets, and self-serve portal submissions. Every format is different. Nothing is clean.
Route that straight into an AI agent and you’re burning reasoning power, and tokens, just to parse inconsistent files before any real decision gets made.
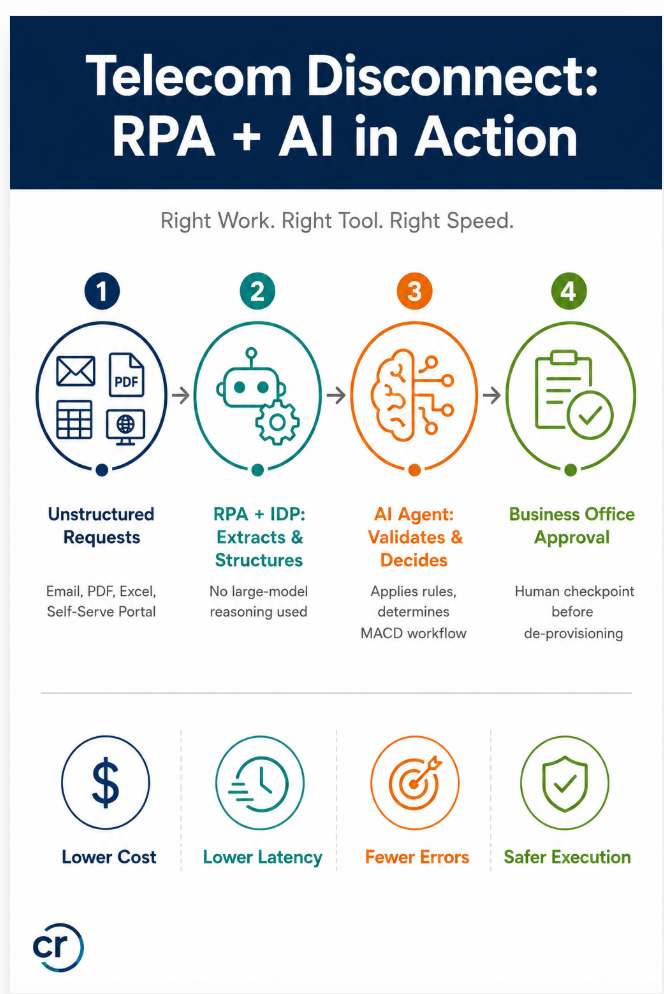
The infographic shows the four-step pipeline that handles it instead: unstructured requests in, RPA with IDP to extract and structure them, an AI agent to validate and decide, and the Business Office to approve before anything is de-provisioned.
A better pipeline, not a smarter model
RPA reads the inputs and extracts the structured fields — Account ID, Service ID, Site, Service Type, Disconnect Date. For the messier formats, that’s RPA paired with OCR/IDP (Intelligent Document Processing): lightweight, purpose-built extraction, not a large reasoning model, running in parallel across hundreds of files at once.
That matters for more than cost. It’s latency. Deterministic extraction processes a batch in parallel, in seconds, with predictable speed every time. Route the same batch through an LLM one file at a time and you’re serialized, slower, and paying for reasoning you don’t need yet.
The AI agent takes it from there — validating the clean data, catching inconsistencies, applying business rules, and determining the right workflow (Move, Add, Change, or Disconnect) before generating the order.
The Business Office still reviews and approves before anything is de-provisioned. In telecom, a wrong disconnect isn’t a minor error — it’s a customer and revenue problem. Automation speeds up the decision; it doesn’t replace the checkpoint.
Where the savings actually come from
RPA absorbs the repetitive, deterministic load — faster and in parallel. AI spends its tokens only where judgment is actually required. Lower cost, lower latency, faster cycle time — and none of it required a smarter model, just a better pipeline.
The savings aren’t hypothetical. They show up the first time you stop asking an LLM to do a parser’s job.
The next wave of enterprise automation won’t be “RPA vs. agentic AI.” It’ll be RPA and agentic AI running as one pipeline, each doing the part it’s actually good at.